Robot actions in 267 ms on a laptop.
An inference engine for Apple Silicon. Language, vision and action models on the GPU and the Neural Engine, measured against PyTorch, MLX and llama.cpp.
Same model, a third of the time
Every stage of SmolVLA runs on the Neural Engine through Core ML. The vision towers are 70% of what is left, and attention inside them is the part nothing has made faster yet.
Benchmarks
Median of interleaved rounds (three, or two for the LLM) per configuration, one process each, plugged in, nothing else on the GPU. The baselines run their fastest setting on the same machine.
Where it loses
tokens per second on a 512-token prompt, llama.cpp against the engine's own decoder (Qwen2.5-0.5B, f16). Decode is ahead; the prompt is not yet.
tokens per second at 4-bit, MLX-LM against llama.cpp's Q4_K_M. Quantized files run on llama.cpp inside the engine, so it inherits that number.
more error in the SmolVLA action chunk on the Neural Engine (1.2e-2) than on the GPU (7.5e-4). The speed costs precision.
What moved the numbers
Each change was measured before and after, one at a time. One of these made things worse, and one was a measurement error.
Use it from Python, C++ or a terminal
# pip install dooms-cpp
import dooms

llm = dooms.LLM("qwen2.5-0.5b-instruct-q4_k_m.gguf")
print(llm.chat([{"role": "user", "content": "Name three colours."}], max_new_tokens=48))

for piece in llm.stream("Once upon a time", 200, temperature=0.8, seed=1):
    print(piece, end="", flush=True)

vla = dooms.VLA.from_dir("models/smolvla")
actions = vla.infer([cam1, cam2, cam3], "pick up the red cube", state)
// find_package(dooms 0.5 REQUIRED) target_link_libraries(app PRIVATE dooms::dooms)
#include <dooms/dooms.hpp>
dooms::Llm llm("qwen2.5-0.5b-instruct-q4_k_m.gguf");
std::string answer = llm.chat({{"user", "Name three colours."}}, 48);
llm.generate("Once upon a time", 200, {0.8f, 40, 0.95f, 1.0f, 1}, {"\n\n"},
[](const std::string & piece) { std::cout << piece; return true; });dooms-cli llm --model qwen2.5-0.5b-instruct-q4_k_m.gguf \
--prompt "Name three colours." --max-tokens 64 --stats
dooms-cli vlm --image photo.jpg --prompt "Describe this image." --models models/smolvlm
dooms-cli vla --models models/smolvla --prompt "pick up the cube" \
--camera a.jpg --camera b.jpg --camera c.jpg --state 0,0,0,0,0,0- Any GGUF
- Every architecture and quantization llama.cpp loads, with chat templates, streaming, stop strings and seeded sampling.
- Self-contained
- The wheel and the SDK carry their own libraries. No build tree, no Xcode project.
- Apple Silicon only
- Metal on the GPU, Core ML for the Neural Engine, Accelerate on the CPU.
- Apache-2.0
- The engine and bindings. Models keep their own licences and are never bundled.
Open source, Apache-2.0

Other things we built
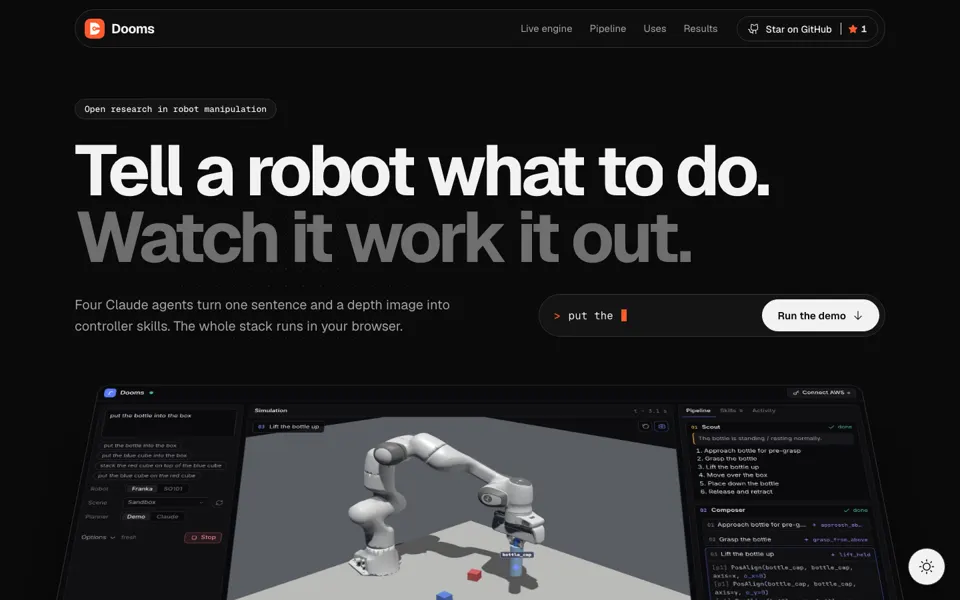
Dooms Inference
One sentence and one depth image become controller skills for a robot arm. Four Claude agents plan; MuJoCo runs it in your browser.
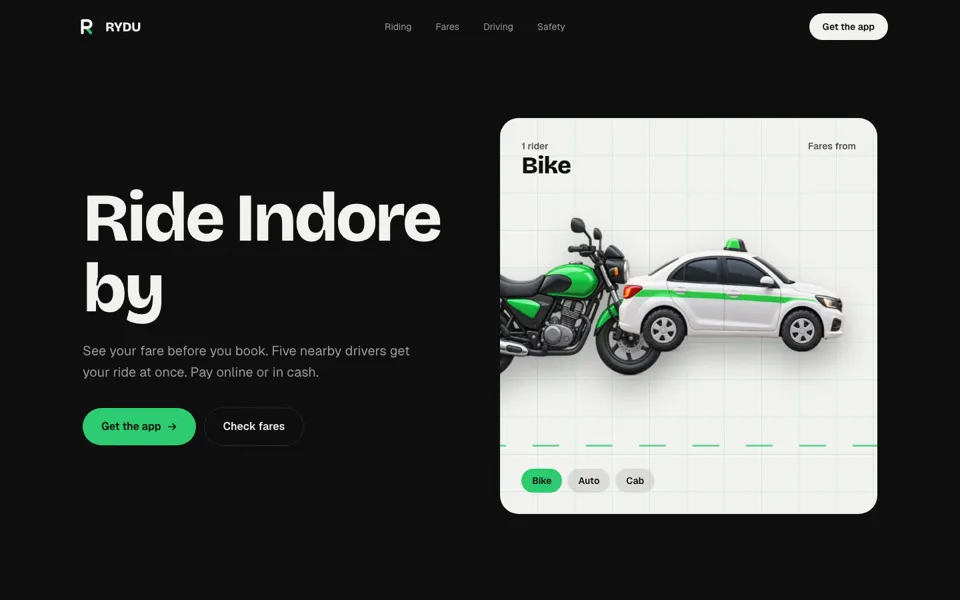
RYDU
Bike, auto and cab rides in Indore. See the fare before you book, and five nearby drivers get your request at once.
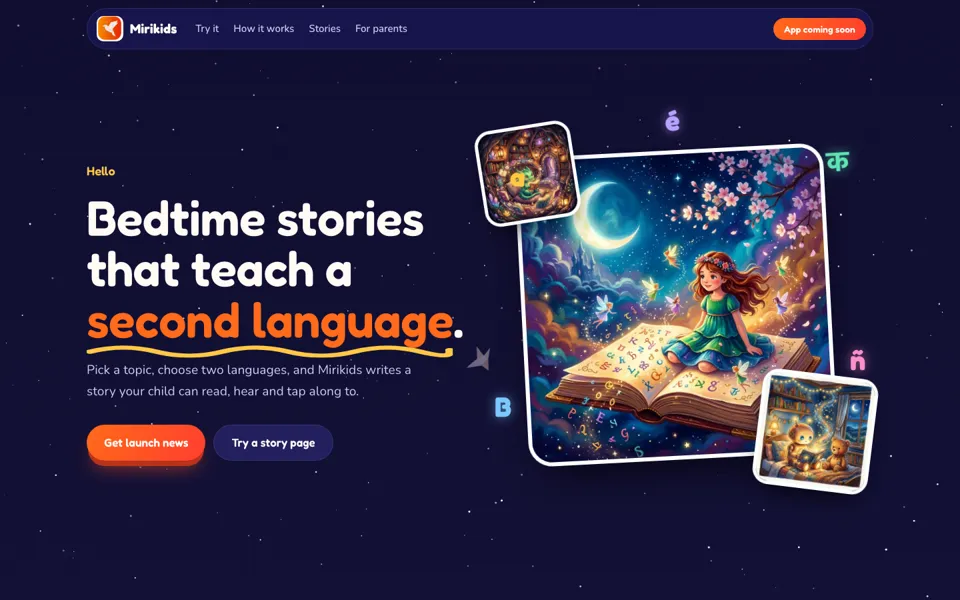
Mirikids app coming soon
Bedtime stories in two languages that children can read, hear and tap along to.